
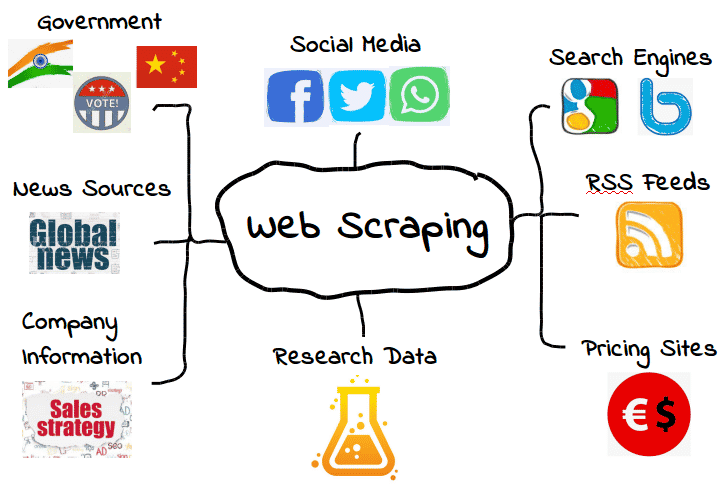
Within the electronic grow older, information is really a effective resource. Companies, scientists, as well as enthusiasts as well tend to be progressively embracing internet scraping to gather useful info through web sites. In the event that you’re a new AI Powered Web Scraping comer to the idea, don’t be concerned! This particular manual can help you know very well what internet scraping is actually, exactly how this functions, and also the resources as well as methods you should use to get going.
What’s Internet Scraping?
Internet scraping may be the procedure for removing information through web sites. This could include collecting info from the solitary web page or even several webpages over the internet. Scraping is advantageous with regard to a number of programs, for example checking costs, collecting get in touch with info, accumulating product critiques, or even producing information with regard to studies.
The reason why Make use of Internet Scraping?
The reason why with regard to utilizing internet scraping tend to be varied. Here are some crucial advantages:
Information Selection: Automatic scraping enables effective assortment of considerable amounts associated with information that might be tiresome to collect by hand.
Researching the market: Companies may monitor rivals, evaluate developments, as well as obtain experience in to client choices.
Information Aggregation: Journalists as well as writers may put together info through several resources quickly.
Individual Tasks: Enthusiasts may clean information with regard to individual pursuits, for example monitoring sports activities data or even examining social networking developments.
Knowing the fundamentals
Prior to scuba diving in to internet scraping, it’s vital that you understand several basic ideas:
HTML as well as CSS
Webpages are made utilizing HTML (Hypertext Markup Language) as well as designed along with CSS (Cascading Design Sheets). Knowing the actual framework associated with HTML can help you determine the information you need to clean. Components for example
, , as well as are generally accustomed to arrange content material.
HTTP Demands
Whenever you entry the web site, your own internet browser transmits a good HTTP (Hypertext Move Protocol) ask for towards the server web hosting which web page. Within internet scraping, a person imitate this method utilizing encoding ‘languages’ or even scraping resources. The actual server after that transmits back again a good HTML reaction that you could parse in order to draw out information.
Parsing Information
When you have the HTML reaction, the next thing is parsing the information. This requires utilizing your local library or even resources in order to get around the actual HTML framework as well as find the particular information factors you’ll need.
Resources as well as Your local library with regard to Internet Scraping
There are many resources as well as encoding your local library readily available for internet scraping. Here are a few well-liked choices:
Stunning Soups (Python): The widely-used collection with regard to parsing HTML as well as XML paperwork. It offers Pythonic idioms with regard to iterating, looking, as well as changing the actual parse sapling.
Scrapy (Python): A good open-source as well as effective internet moving construction. It’s well suited for large-scale scraping tasks and may manage demands, adhere to hyperlinks, as well as shop information effortlessly.
Selenium: Something with regard to automating browsers. It’s particularly helpful for scraping powerful web sites which depend seriously upon JavaScript.
Octoparse: The user-friendly, visible internet scraping device that needs absolutely no encoding abilities. It’s ideal for newbies wanting to get began rapidly.
ParseHub: An additional visible internet scraping device which can help you gather information through powerful as well as interactive web sites without having html coding.
How to choose an easy Scraper
In order to demonstrate the procedure associated with internet scraping, let’s stroll via a fundamental instance utilizing Python as well as Stunning Soups.
Step one: Set up Needed Your local library
Very first, you have to set up the required your local library. That you can do this particular utilizing pip:
party
Duplicate signal
pip set up demands beautifulsoup4
2: Create the actual Scraper
Here’s an easy piece of software in order to clean estimates from the test web site:
python
Duplicate signal
transfer demands
through bs4 transfer BeautifulSoup
web address = ‘http: //quotes. toscrape. com/’
reaction = demands. get(url)
soups = BeautifulSoup(response. textual content, ‘html. parser’)
estimates = soups. find_all(‘div’, class_=’quote’)
with regard to quotation within estimates:
textual content = quotation. find(‘span’, class_=’text’). get_text()
writer = quotation. find(‘small’, class_=’author’). get_text()
print(f'”text inch — author ‘)
Step three: Operate Your own Piece of software
Whenever you operate this particular piece of software, this brings the actual web page, parses the actual HTML, as well as concentrated amounts estimates with their writers, exhibiting all of them within the system.
Guidelines as well as Honest Factors
Whilst internet scraping could be a effective device, it’s necessary to adhere to honest recommendations:
Regard Bots. txt: Examine the actual website’s bots. txt document to determine what’s allowable in order to clean.
Restrict Demands: Prevent mind-boggling machines along with a lot of demands within a brief period. Make use of rest times in between demands.
Attribution: If you are using scraped information inside your function, provide correct credit score towards the unique supply.
Summary
Internet scraping starts upward a global associated with options with regard to information selection as well as evaluation. Through knowing the fundamentals as well as making use of the best resources, you are able to successfully collect useful experience on the internet. While you attempt your own scraping trip, keep in mind to stick to honest methods as well as regard the actual privileges associated with site owners. Pleased scraping!